Open to opportunities

Nicolás
Rojas Díaz

Software Developer | Data Engineering

SQL · Python · Azure · Databricks · PySpark · Apache Spark

Software Developer with hands-on data experience and a software engineering foundation, currently deepening my focus on data pipelines, Lakehouse architecture, data modeling and data quality.

Nicolás Rojas Díaz
NR
Software Developer

Professional Profile

I'm a Software Developer with a degree in Ingeniería Civil en Informática, specializing in Information Technologies, from Universidad Católica de Temuco. I'm currently focusing my professional development on Data Engineering.

My background combines software engineering with hands-on experience working with data. During my internships in the Data Governance area at Universidad Católica de Temuco, I first worked on data analysis, validation and reporting, and later completed a Data Engineering-focused internship where I evaluated Data Lake technologies and implementation feasibility, built a local open-source proof of concept, and worked on relational data modeling with SQL Server.

In my current role as a Software Developer, I develop and maintain a production platform for gym operations, working across backend development, databases, APIs and infrastructure. My work includes Go, PostgreSQL, REST APIs, CI/CD pipelines with GitHub Actions, AWS Lightsail and Cloudflare Workers, as well as participation in architecture decisions and technical coordination under Scrum.

I'm currently deepening my Data Engineering skills through end-to-end projects using Azure Data Factory, Azure Data Lake Storage Gen2, Azure Databricks, Apache Spark, PySpark, SQL and Delta Lake, with a focus on historical and incremental ingestion, Medallion architecture, idempotency, data quality, orchestration, security and production deployment practices.

My goal is to continue evolving toward Data Engineering roles where I can combine my software engineering foundation with the design, transformation and reliable delivery of data.

Software Development Data Engineering Azure Databricks CI/CD SQL Python PySpark Apache Spark Data Modeling
  • Current role Software Developer
  • Company Nissi Advisor S.P.A.
  • Focus Data Engineering
  • Education Ingeniería Civil en Informática
  • University Universidad Católica de Temuco
  • Availability Open to opportunities
  • Email Nicord2002@gmail.com

Professional Experience

Dec 2025 - Present

Software Developer

Nissi Advisor S.P.A.

Develop and maintain a production platform for gym operations, contributing across backend development, databases, CI/CD and infrastructure.

  • Develop backend services in Go and REST APIs supporting customer management, planning and administrative workflows.
  • Design and maintain PostgreSQL data models and automate operational processes used in day-to-day gym management.
  • Design and maintain CI/CD pipelines with GitHub Actions for a Go backend and Next.js frontend, including build validation on pushes and Pull Requests and automated production deployments.
  • Implement CI/CD workflows with build validation, artifacts, post-deployment health checks and rollback mechanisms to reduce deployment risk.
  • Automate backend and frontend deployments to cloud infrastructure using GitHub Actions, AWS and Cloudflare, securely managing credentials and configuration variables.
  • Contribute to software architecture, technical implementation decisions and the evolution of the platform, while coordinating technical work on the mobile application.
GoPostgreSQLREST APIsData ModelingGitHub ActionsCI/CDNext.jsAWSAWS LightsailLinuxCloudflare WorkersScrumGit
Nov 2024 - Jan 2025

Data Engineering Intern

Universidad Católica de Temuco

Conducted a feasibility study for the potential adoption of a Data Lake within the university's Data Governance area.

  • Researched Data Lake architectures and compared implementation approaches, cost considerations and trade-offs across AWS, Azure, Google Cloud and open-source technologies.
  • Built a local Data Lake proof of concept with Docker using MinIO, Trino, Hive Metastore, PostgreSQL and Metabase to validate the basic architecture and SQL querying workflow.
  • Designed a 13-table relational database in SQL Server, including the data model, SQL queries, data dictionary and data loading documentation.
  • Used AI-assisted text extraction on scanned post-it images, followed by manual validation, correction and classification before loading the structured information into the database.
  • Created Tableau dashboards to explore and present the resulting data to the Data Governance team.
SQLSQL ServerData ModelingDockerPostgreSQLMinIOTrinoHive MetastoreMetabaseTableauData Lake
Jan 2024 - Jun 2024

Data Analyst Intern

Universidad Católica de Temuco

Supported the Data Governance team in the analysis, management and validation of institutional data.

  • Analyzed and validated institutional information used for reporting and operational monitoring.
  • Developed dashboards and reports using Tableau and Power BI to support decision-making and KPI monitoring.
  • Used SQL to query and prepare data for analysis and visualization.
SQLPower BITableauData AnalysisData VisualizationData Validation

Selected Projects

Hands-on projects focused on Data Engineering, data platforms and reliable data pipelines.

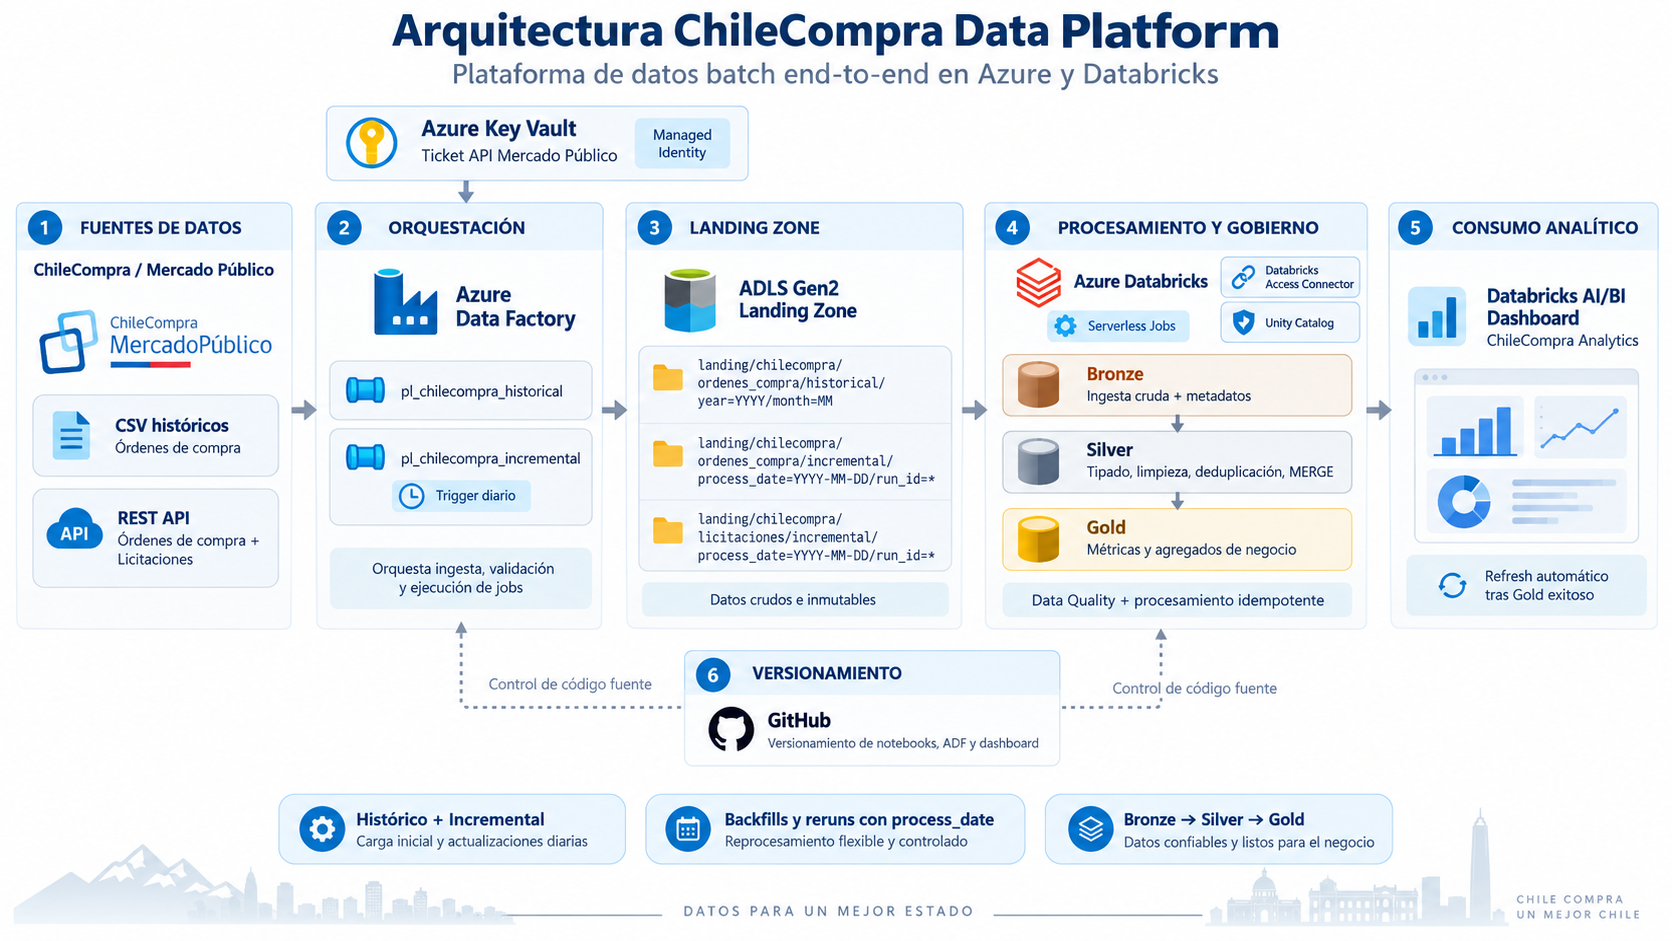
ChileCompra Data Platform architecture on Azure using Data Factory, ADLS Gen2, Databricks and a Medallion architecture
Data Engineering · Azure & Databricks

ChileCompra Data Platform

End-to-end batch Data Engineering platform built on Azure to process more than 1.1 million purchase orders and 2.8 million line items from Mercado Público / ChileCompra, combining historical CSV ingestion with daily incremental ingestion from REST APIs, orchestrated with Azure Data Factory and Databricks Jobs.

Azure Data Factory ADLS Gen2 Azure Databricks PySpark Spark SQL Delta Lake Unity Catalog Azure Key Vault GitHub Actions
  • Implemented a Medallion architecture (Landing → Bronze → Silver → Gold) and automated the daily pipeline with Azure Data Factory and Databricks Jobs; purchase order and tender branches converge before five independent Gold transformations executed in parallel.
  • Implemented idempotent and recoverable processing using process_date, run_id, replaceWhere, Delta MERGE and freshness rules, supporting reruns and backfills without generating duplicates or overwriting newer versions.
  • Added critical pre-write and post-write Data Quality controls for keys, duplicates, statuses and referential integrity; critical inconsistencies stop the task and propagate the failure from Databricks to Azure Data Factory.
  • Configured service-to-service security with Azure Key Vault, Managed Identity, Azure RBAC, Databricks Access Connector and Unity Catalog, and automated the refresh of a Databricks AI/BI dashboard only after all Gold tasks complete successfully.
1.1M+ Purchase orders processed
2.8M+ Line items processed
5 Parallel Gold transformations

All notebooks, Azure Data Factory pipelines and the analytics dashboard are version-controlled in GitHub.
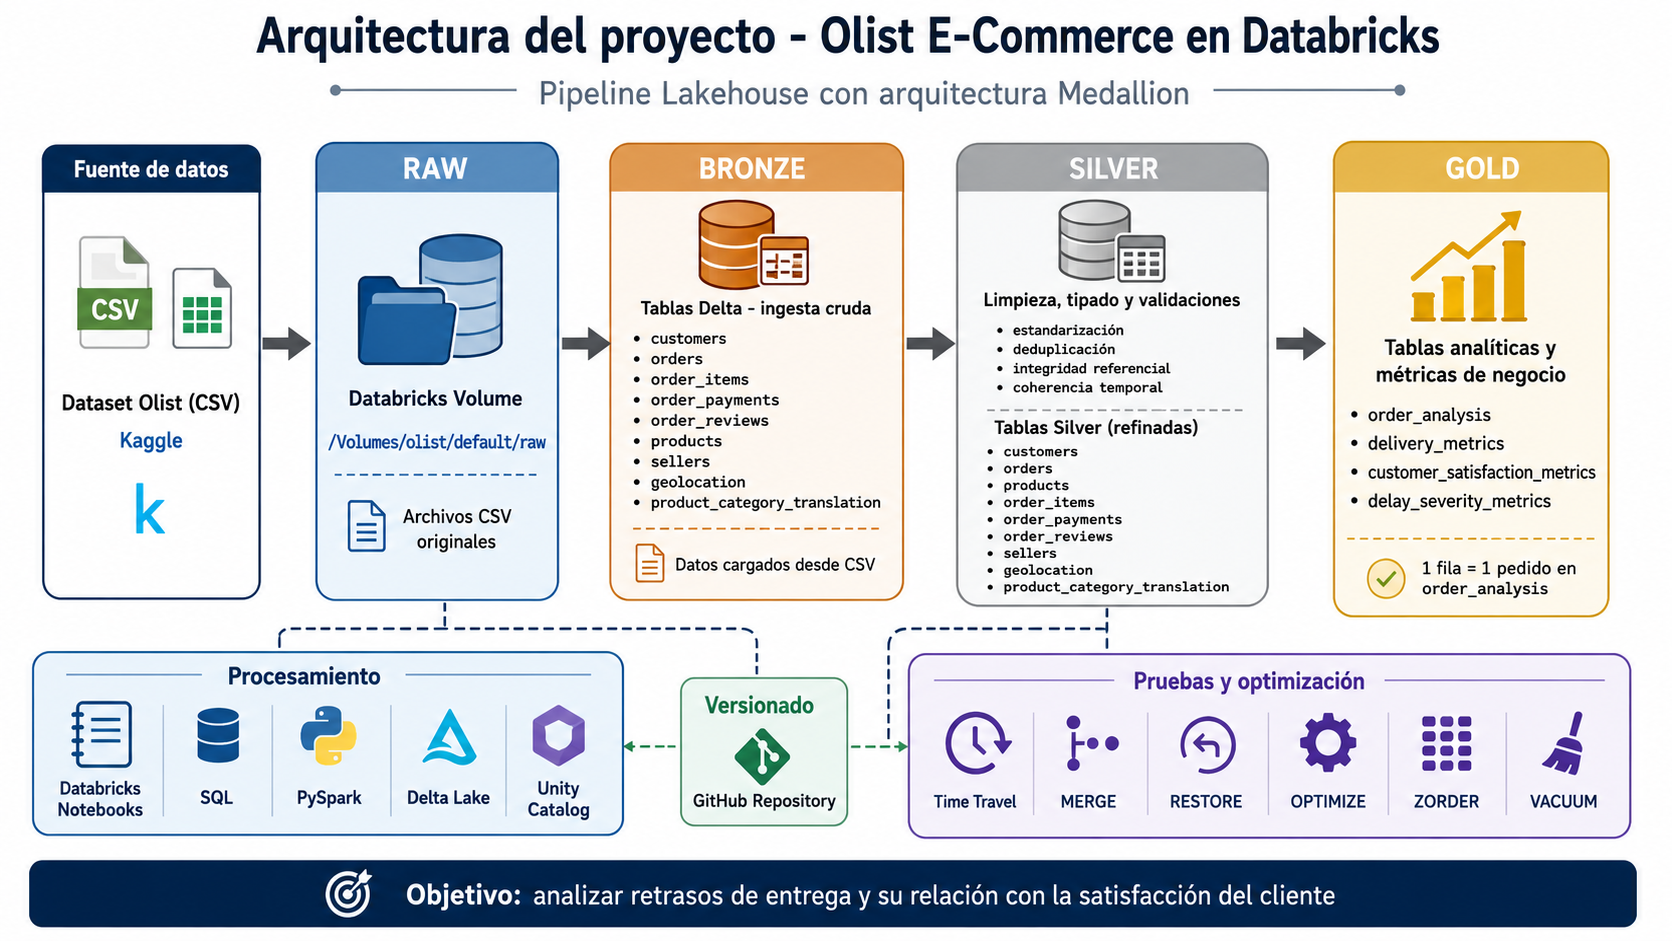
Olist Databricks Lakehouse architecture using Raw, Bronze, Silver and Gold layers
Data Engineering · Databricks

Olist E-Commerce Lakehouse Pipeline

End-to-end Data Engineering project built in Databricks using the Brazilian E-Commerce dataset by Olist. The pipeline follows a Raw → Bronze → Silver → Gold Medallion architecture, transforming raw CSV data into validated Delta tables and analytical datasets focused on delivery performance and customer satisfaction.

Databricks PySpark Apache Spark SQL Delta Lake Unity Catalog Git / GitHub
  • Built a Raw → Bronze → Silver → Gold Lakehouse architecture in Databricks.
  • Implemented data cleaning, standardization, relational validation and data quality controls before creating analytical Gold tables.
  • Tested Delta Lake capabilities including MERGE, Time Travel, RESTORE, OPTIMIZE, ZORDER and VACUUM.
  • Analyzed 99,441 orders and identified a strong association between delivery delays and negative customer reviews.
99,441 Orders analyzed
9.31% Negative reviews - orders without delay
62.46% Negative reviews - delayed orders

Delta Lake capabilities explored: Transaction Log, Time Travel, UPDATE, DELETE, RESTORE, MERGE, OPTIMIZE, ZORDER and VACUUM.

Skills & Tech Stack

Azure

Azure Data Factory Azure Data Lake Storage Gen2 Azure Key Vault Managed Identities Azure RBAC

Databricks

Azure Databricks Delta Lake Unity Catalog Databricks Jobs

Databases

PostgreSQL Microsoft SQL Server

Software Development & CI/CD

Go REST APIs Git GitHub GitHub Actions CI/CD Docker Linux Scrum

Cloud / Infrastructure

AWS AWS Lightsail Cloudflare Workers DigitalOcean

Analytics

Power BI Tableau GPT/LLM Prompt Design

Domain Knowledge

Mining

Education & Certifications

Education

Universidad Católica de Temuco

Ingeniería Civil en Informática

Specialization: Information Technologies · Mar 2020 - Aug 2025

Five-year engineering degree in Informatics with a specialization in Information Technologies.

Academic background in software development, databases, data analysis and information systems.

View degree PDF

Certifications

Data / Technology

Data / Technology

Google Data Analytics Professional Certificate

Professional certificate

Data / Technology

Google AI Essentials

Professional certificate

Contact

Open to Data Engineering and software engineering opportunities, including remote roles.